
Models & benchmarks
28 articles
A new frontier model lands most weeks and almost every launch claims a benchmark win. These articles audit those claims: what a model costs per million tokens, where it fails, how open weights compare to hosted APIs, and which numbers matter once a model is inside a workflow. Comparisons are run on hardware we own, and the method is always stated.
Page 2
Showing 21 to 28 of 28
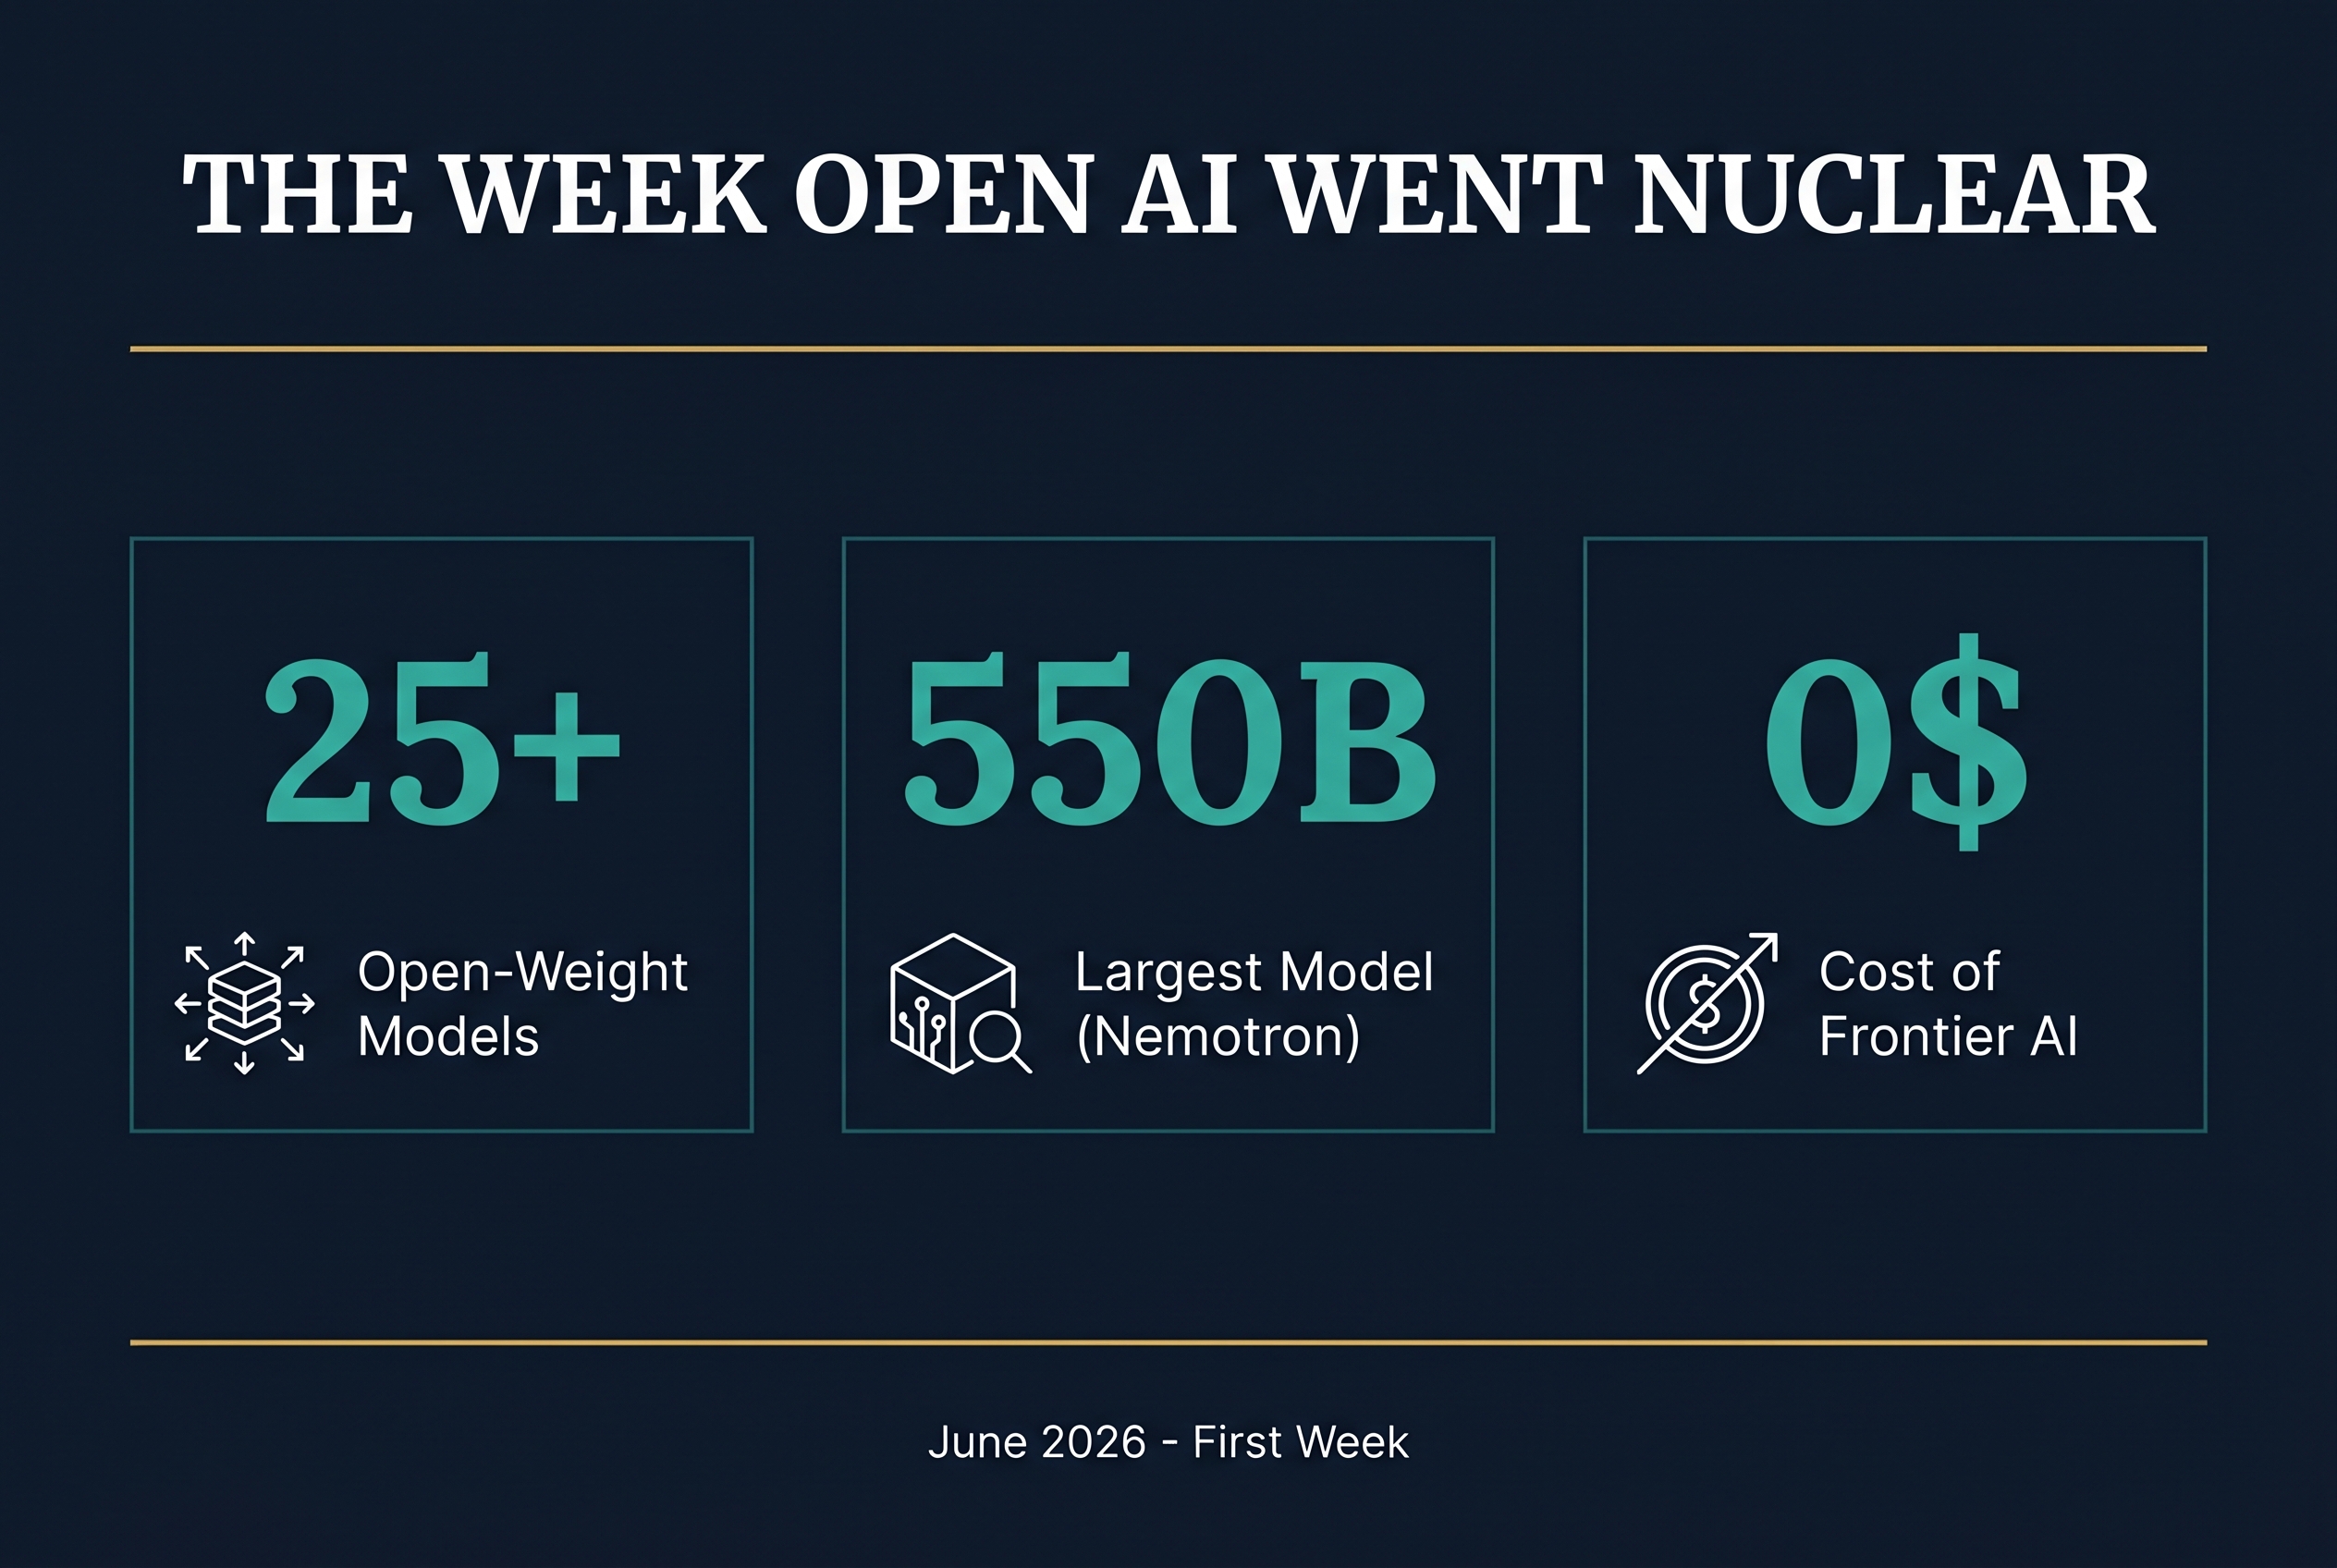
The Week Open-Source AI Went Nuclear: 25+ Open-Weight Drops That Changed Everything
25+ frontier open-weight AI models dropped in one week across every modality. The full breakdown of the most insane week in open-source AI history.
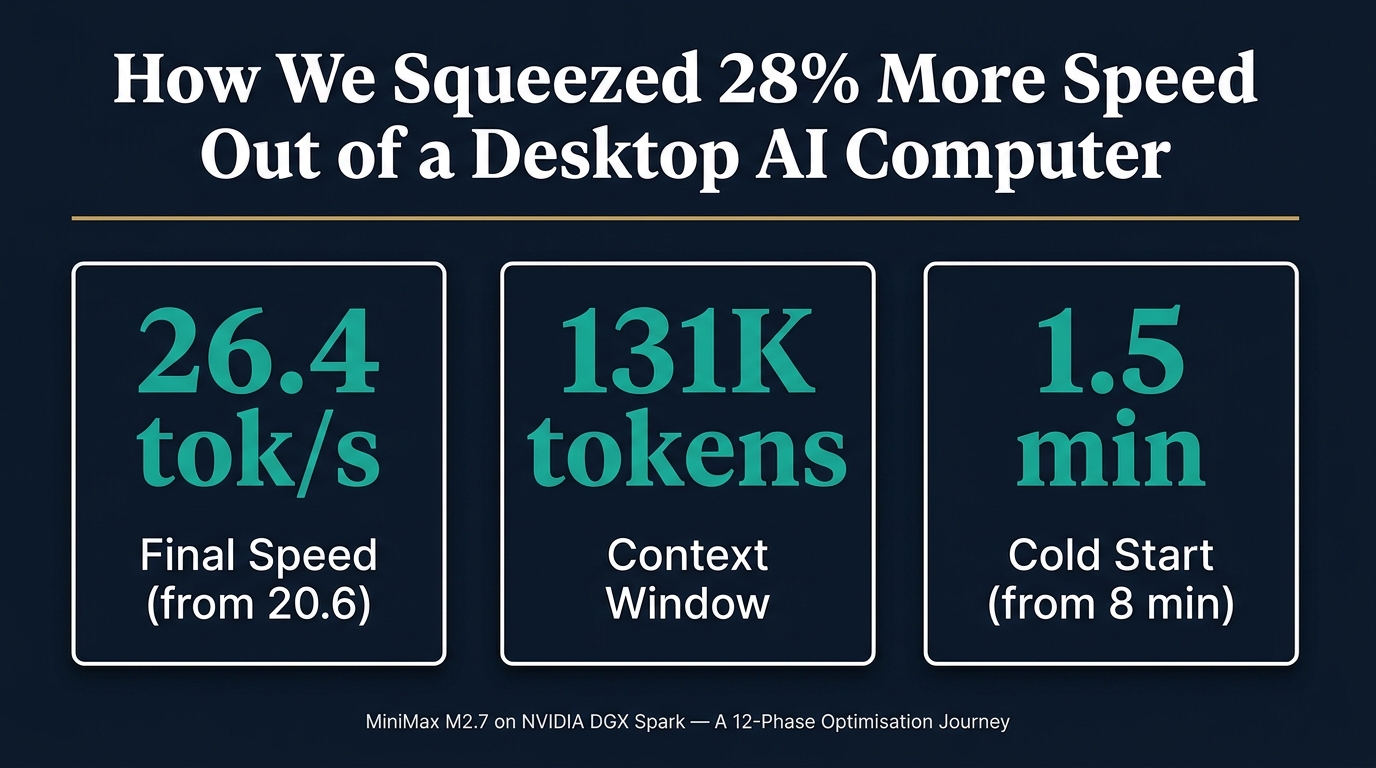
How We Optimised a 229 Billion Parameter AI Model on a Desktop Computer: A 12-Phase Journey
We deployed MiniMax M2.7 (229B params) on a single NVIDIA DGX Spark and spent a day optimising it. Thread tuning added 12% speed, --no-mmap cut cold start from 8 min to 90 seconds, and we discovered a GCC bug on Grace CPU. Full breakdown of what worked and what did not.
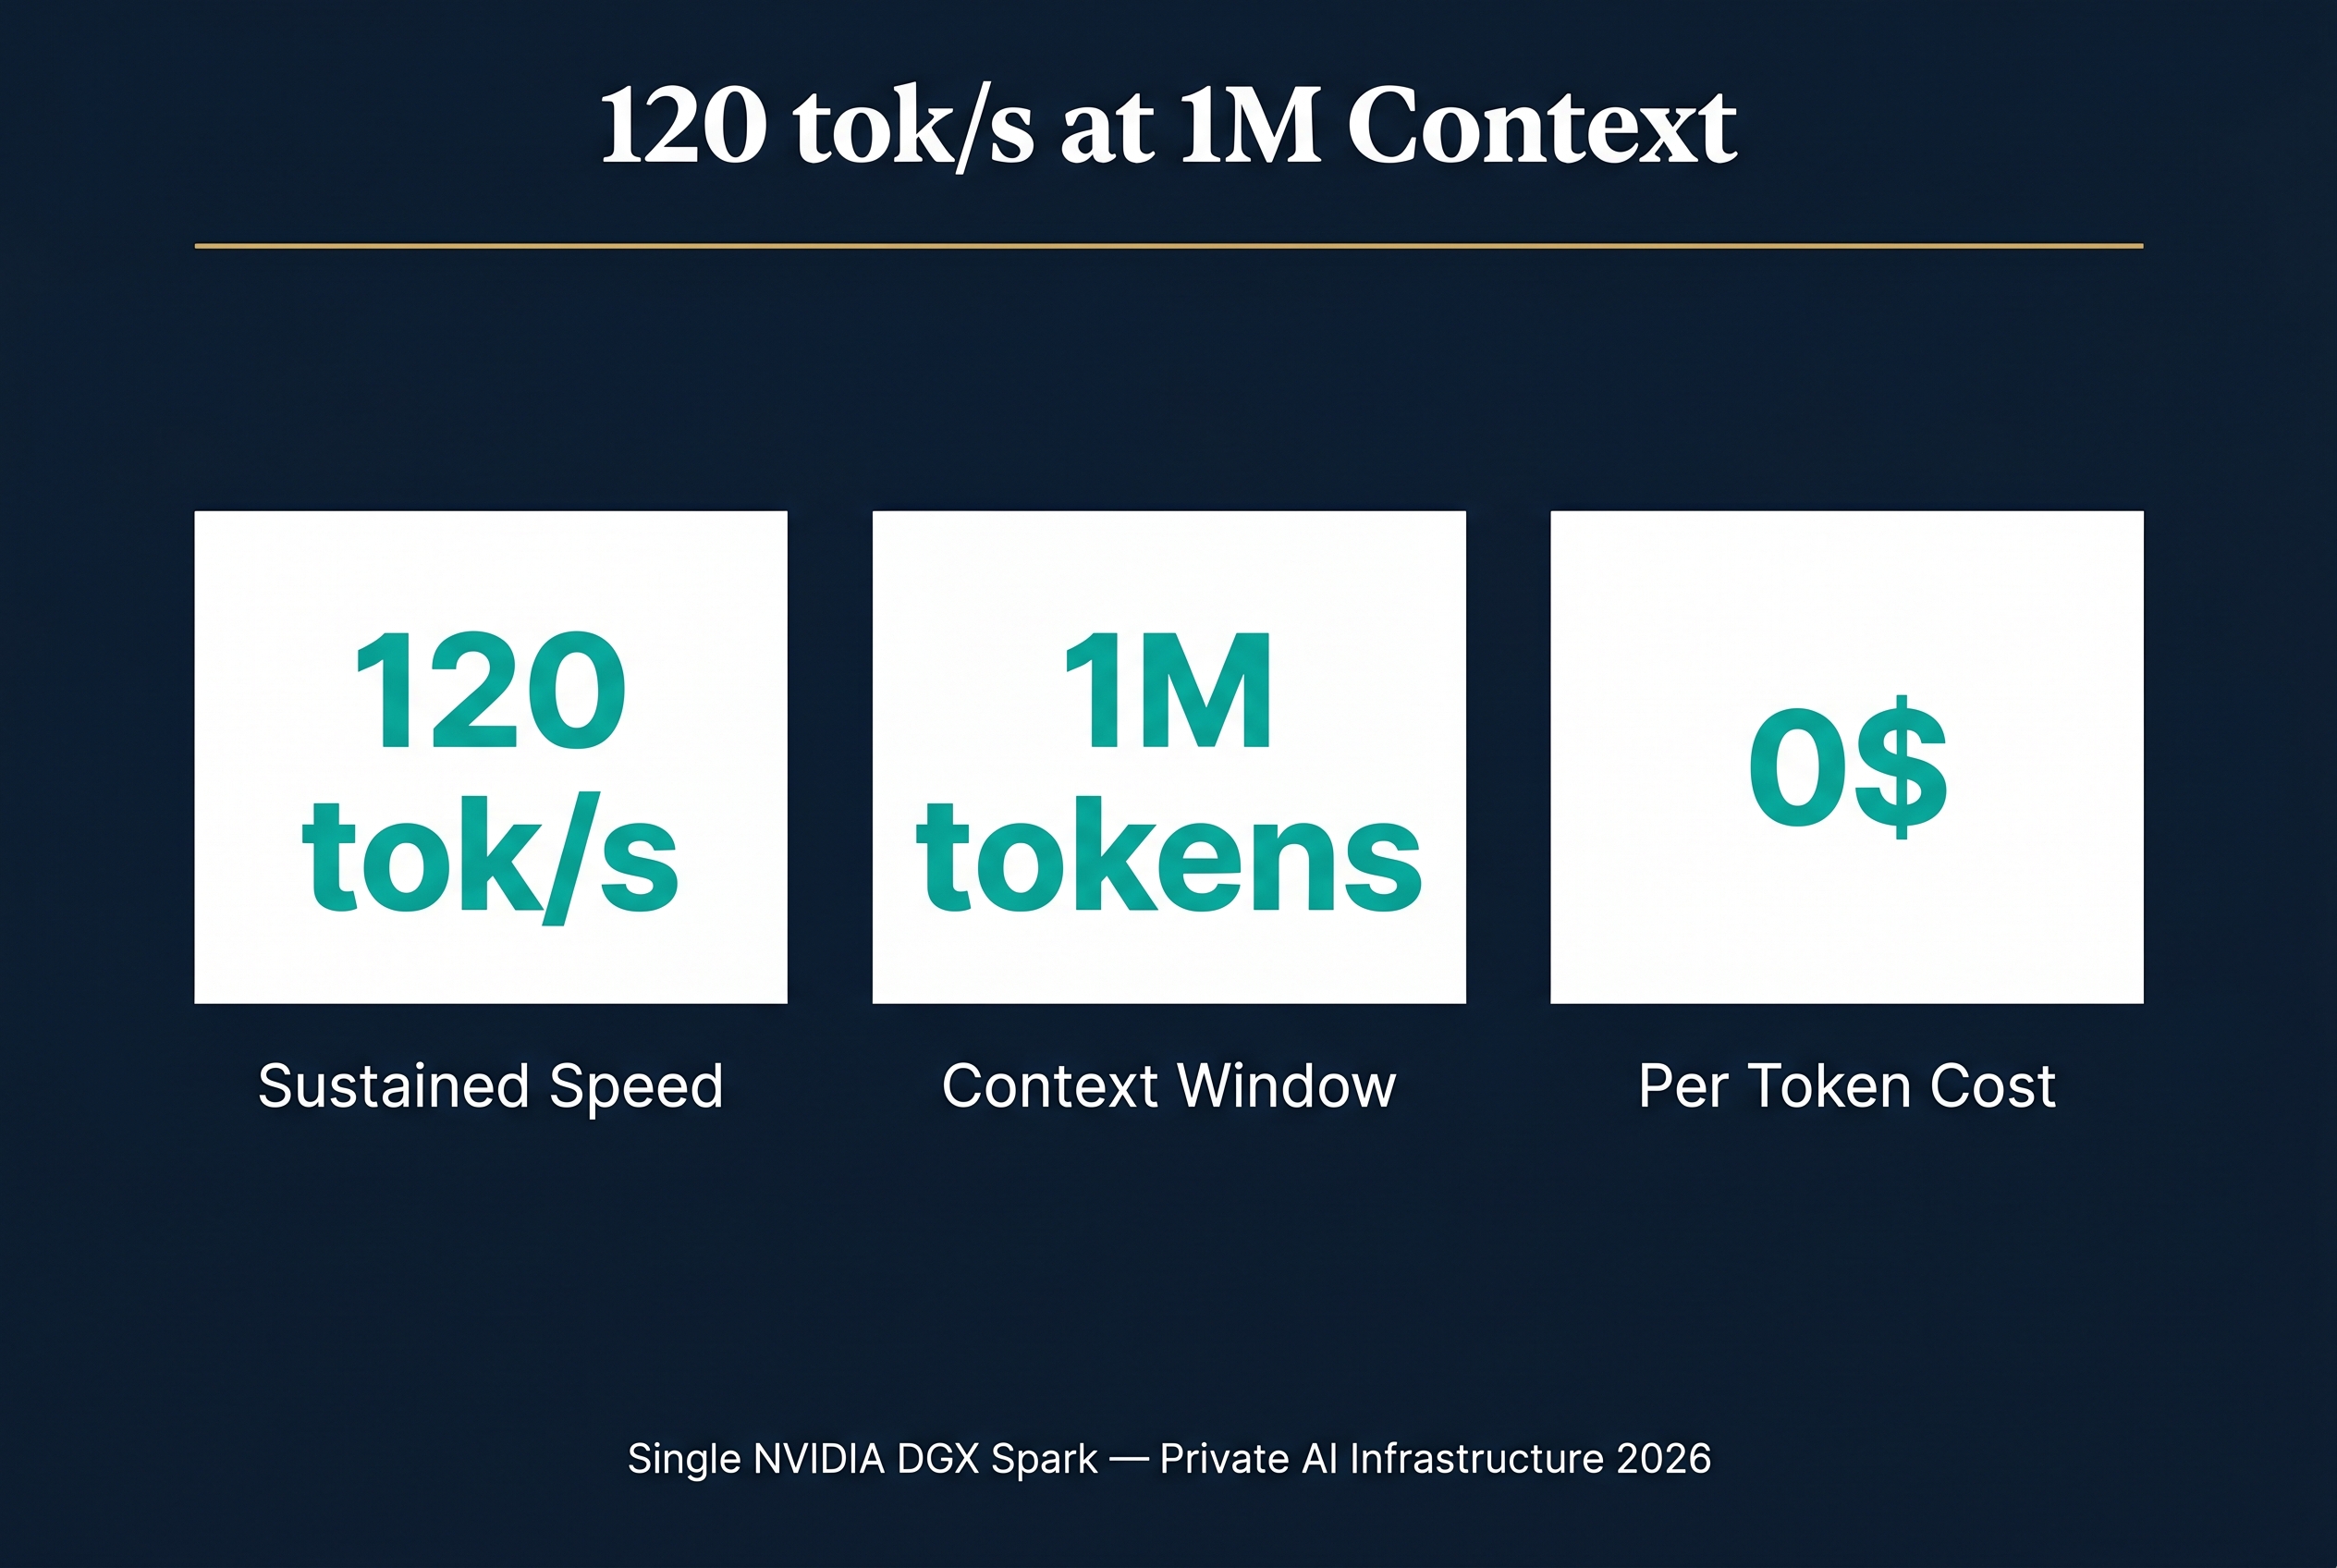
We Hit 120 Tokens Per Second With 1 Million Token Context on a Single Desktop AI Computer
How we achieved 120 tok/s with 1 million token context on a single NVIDIA DGX Spark using Atlas and Qwen 3.6 NVFP4. Zero regression, 100% retrieval accuracy, zero per-token cost.
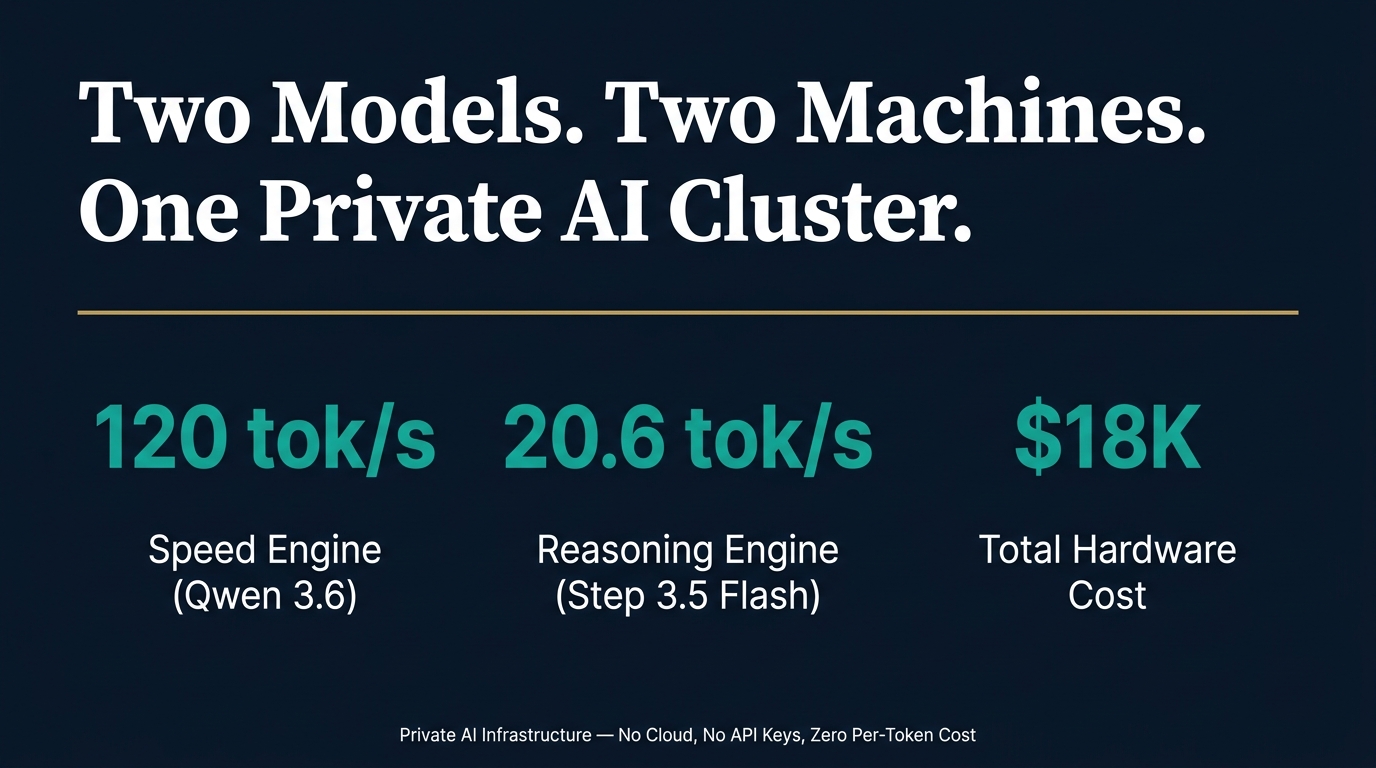
Why We Run Two AI Models on Two Desktop Computers Instead of One Big One
How a two-model private AI cluster using Qwen 3.6 (120 tok/s) for speed and Step 3.5 Flash (20.6 tok/s) for reasoning outperforms a single-model setup. Built on two NVIDIA DGX Sparks for $18K AUD with zero ongoing costs.
DeepSeek V4 vs GPT-5.5 vs Claude Opus vs GLM: Cost and Benchmark Comparison for AI Agent Fleets
DeepSeek V4, GPT-5.5, Claude Opus, and GLM compared on cost, benchmarks, and self-hosting viability for autonomous AI agent fleets.
The Best Chinese AI Model for OpenClaw: GLM-5 vs Kimi K2.5 vs MiniMax M2.5
Comprehensive comparison of GLM-5, Kimi K2.5, and MiniMax M2.5 for OpenClaw autonomous agents. MiniMax M2.5 delivers 80.2% SWE-Bench performance at 62% lower cost than competitors.

Why AI Benchmarks Don't Matter (And What to Look at Instead)
Why AI Benchmarks Don't Matter (And What to Look at Instead)

ChatGPT vs DeepSeek vs Claude vs Gemini: Which AI Should Australian Businesses Actually Use in 2026?
ChatGPT vs DeepSeek vs Claude vs Gemini: Which AI Should Australian Businesses Actually Use in 2026?

One email, most weeks
What actually changed in AI and what to do about it. No pitch, and you can leave in one click.