
Private AI
8 articles
Plenty of Australian businesses cannot send client data to a US API, and plenty more simply would rather not. These articles cover self-hosted inference on real hardware, what local models can and cannot do yet, the cost of running your own stack, and the compliance questions that decide the architecture before any model is chosen.
Latest
Showing 1 to 8 of 8
Perplexity Portable Computer on DGX Spark: Fully Local AI Agents, Explained
Perplexity Portable Computer runs the entire agent stack: orchestrator, models, harness, and sandbox, locally on NVIDIA DGX Spark with zero per-token costs. What ships, what the benchmarks say, and who should run it.
DeepSeek V4 Flash 0731 on Dual DGX Spark: Why 13B Active Parameters Changes Everything for Private AI Agents
DeepSeek V4 Flash 0731 delivers frontier-level agentic performance with 13B active parameters, 10x smaller than Claude Opus. We run it on two NVIDIA DGX Sparks with Hermes Agent for private, on-prem AI workloads at 41 tok/s. Here is the full setup, cost analysis, and why it changes the economics of running AI agents locally.
Kimi K2.7 Complete Review: Benchmarks, Cost, and Local Inference
Kimi K2.7 achieves GPT-5.5-class performance at a fraction of the cost. Full review with benchmarks, local inference setup, and competitive analysis.
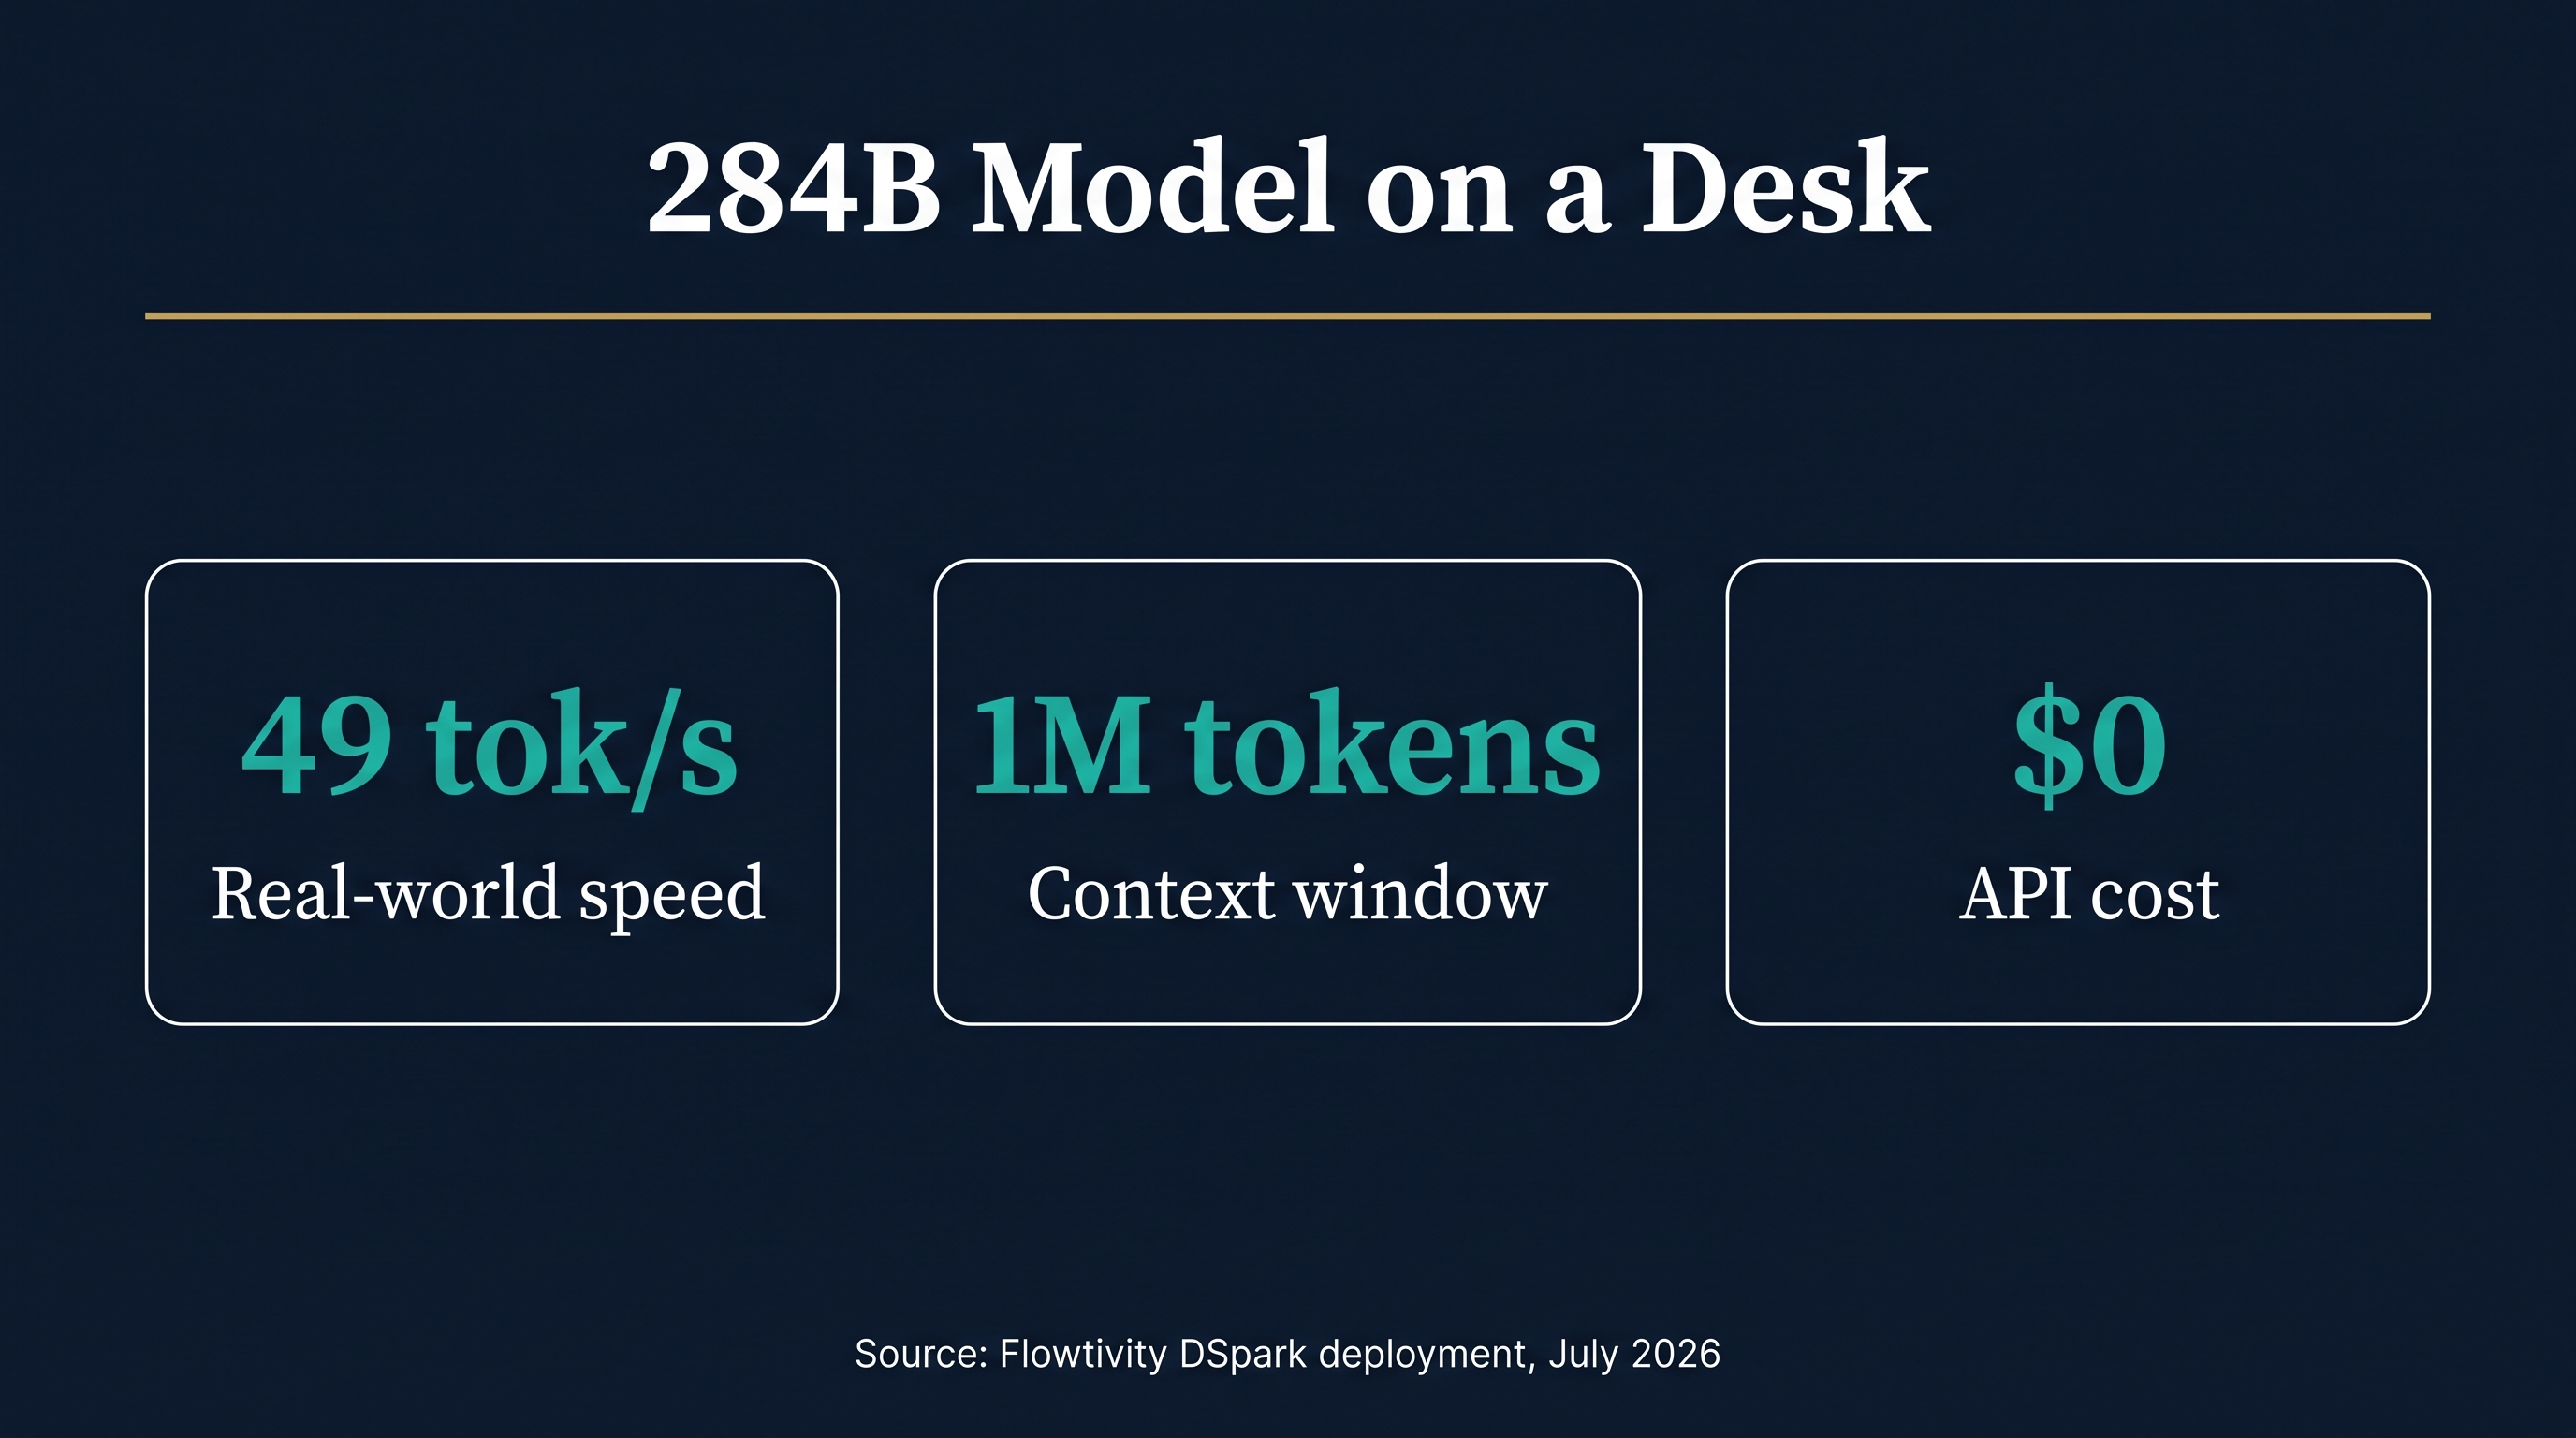
Running a 284B AI Model on Your Desk: Our Real-World DSpark Deployment Log
We deployed DeepSeek V4 Flash with DSpark speculative decoding on 2x NVIDIA DGX Spark boxes. 49 tok/s, 1M token context, 6-way concurrency, zero API bill. Real numbers, real bugs, real fixes.
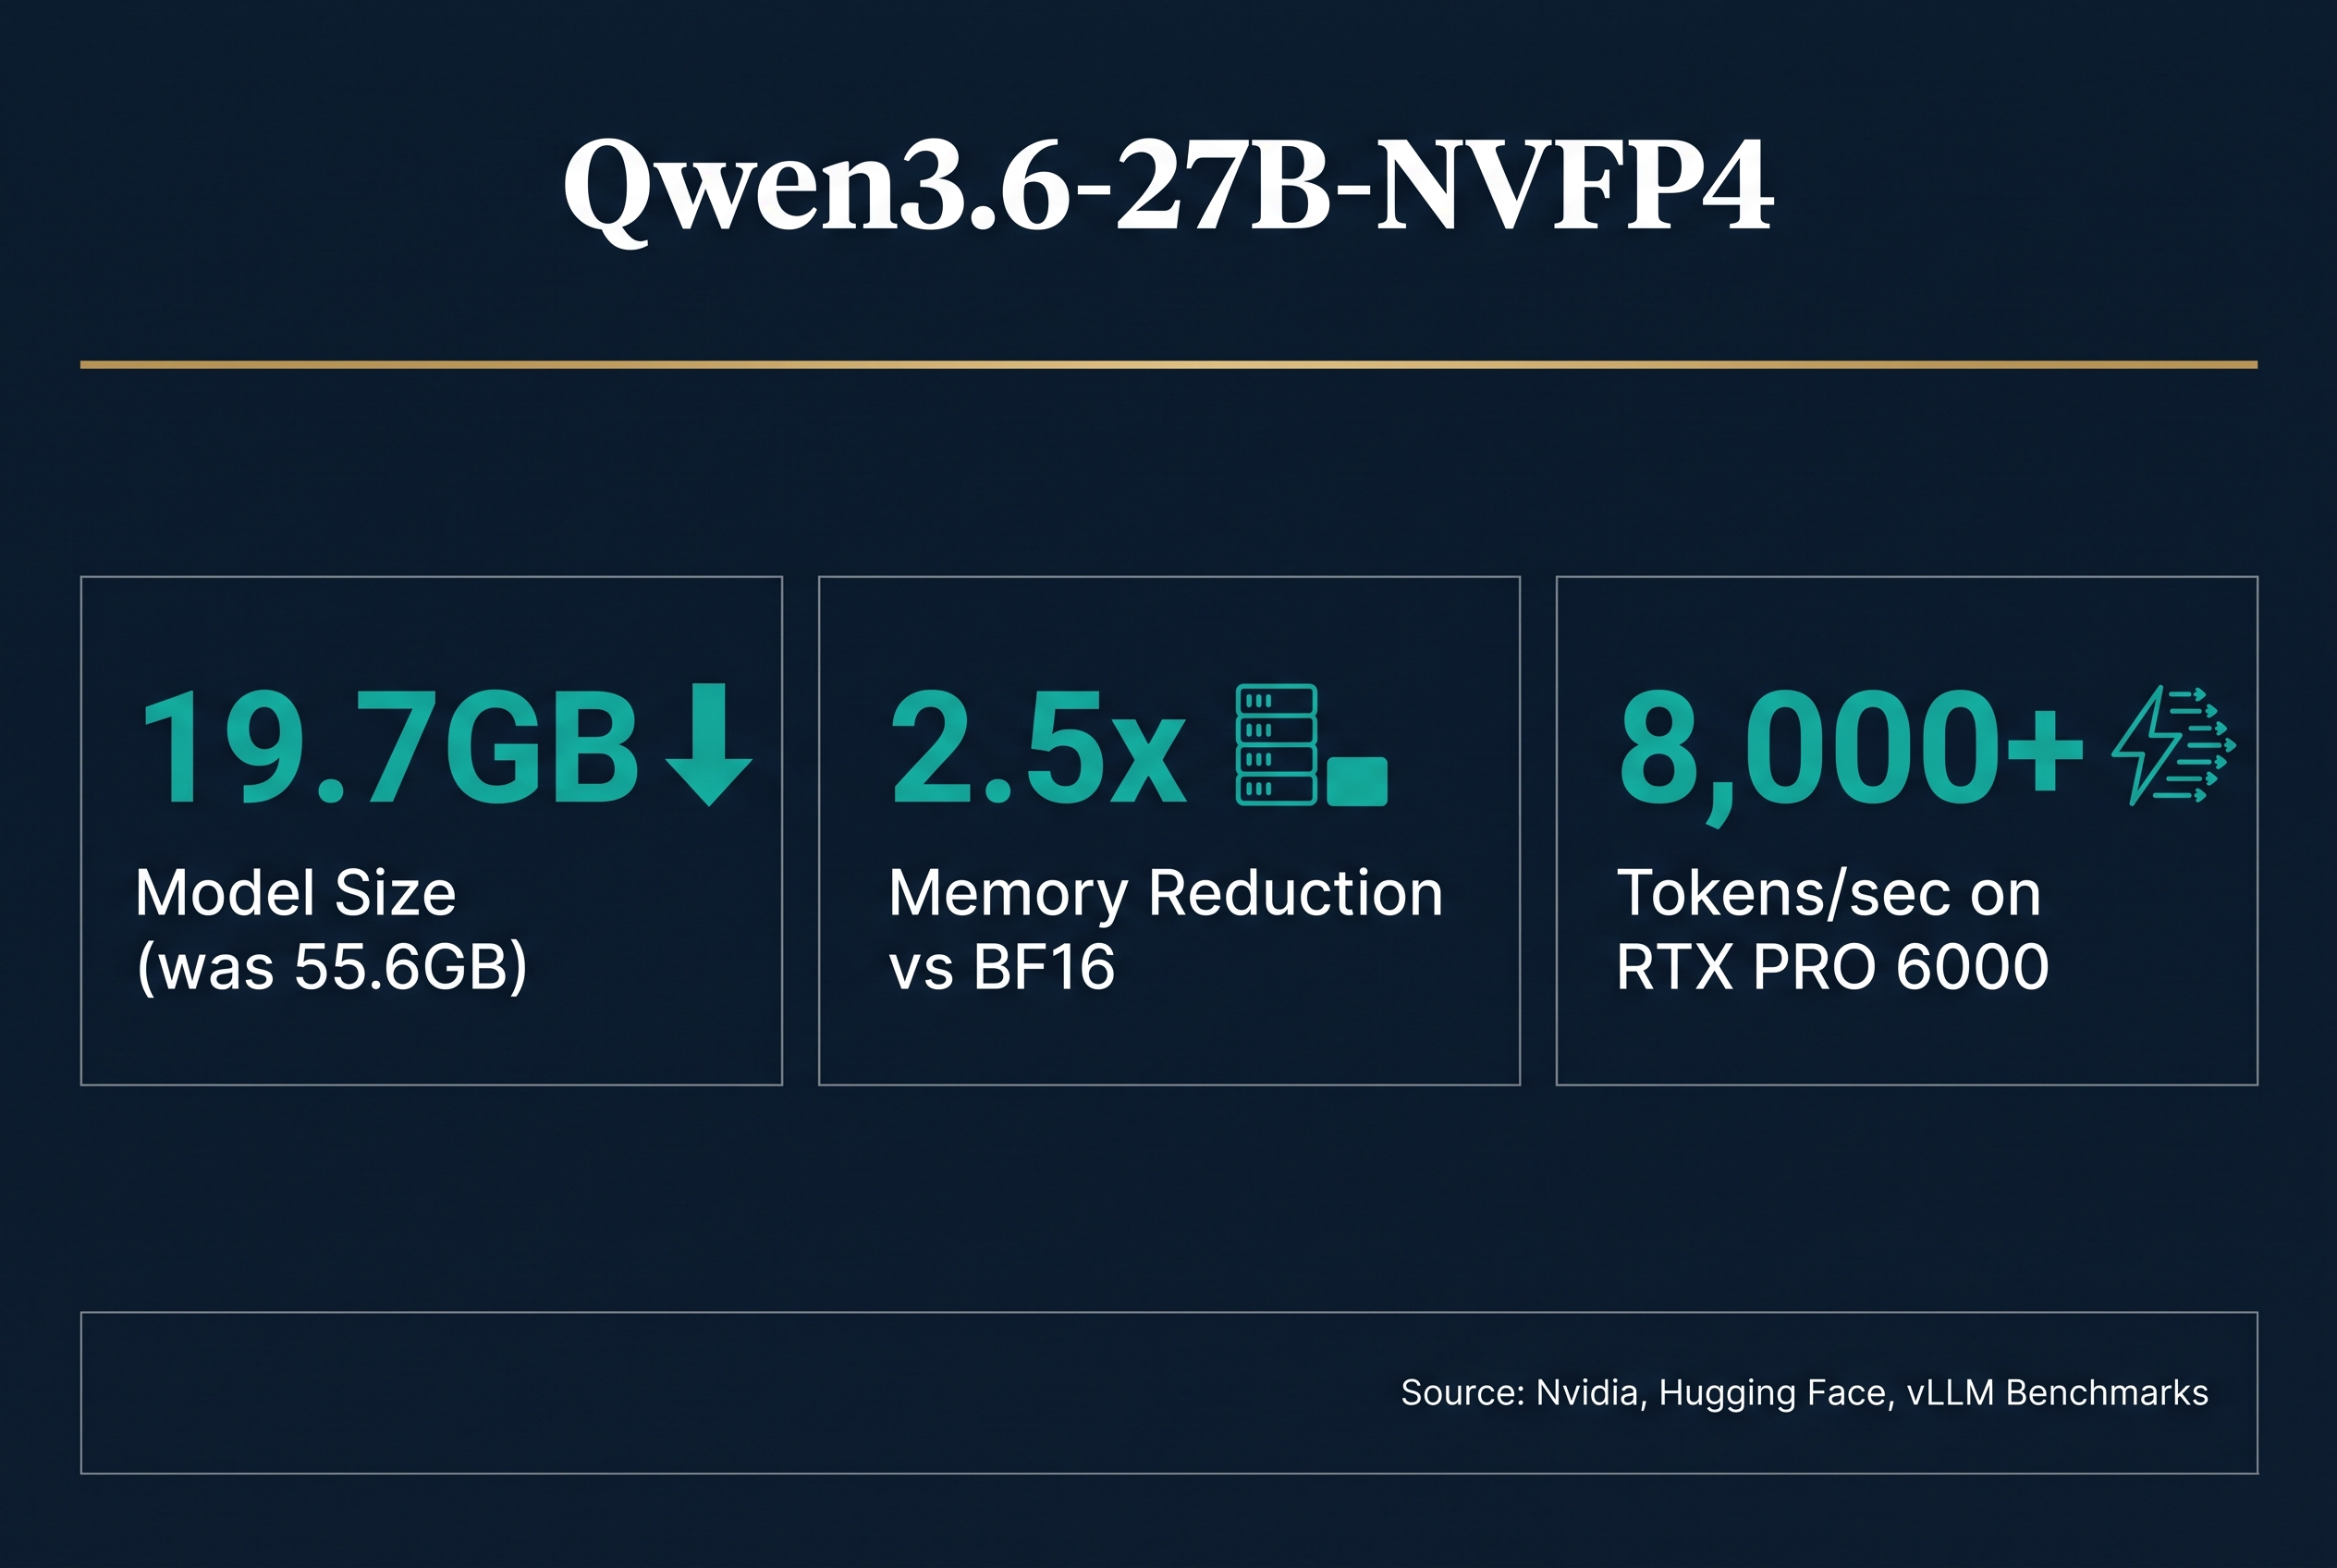
Nvidia's Qwen3.6-27B-NVFP4: 27B Parameter AI Now Runs on Consumer Blackwell GPUs
Nvidia's NVFP4 quantization of Alibaba's Qwen3.6-27B cuts memory by 2.5x with under 1% accuracy loss. The 19.7GB model runs on RTX PRO 6000 and DGX Spark, delivering up to 2,000+ tokens/sec with vLLM and MTP speculative decoding.
We Ran DeepSWE on Local Models. Here's What Actually Happened.
We tested DeepSeek V4 Flash, AEON-27B, and Step 3.7 Flash against the DeepSWE benchmark on DGX Spark hardware. All three scored zero. The story behind that zero is what matters.
Step 3.7 Flash Review: We Tested StepFun's 198B Model on a DGX Spark
StepFun released Step 3.7 Flash on May 29, 2026. We deployed it on our NVIDIA DGX Spark within 24 hours. 100% tool call success rate, SWE-Bench PRO 56.3, ClawEval 67.1 (first place). Here is our first-hand review with benchmark comparisons, local deployment guide, and DGX Spark performance data.
How to Build Your Own Private AI Infrastructure in 2026: Stop Renting Intelligence
Australian businesses are spending $500-$8,000 per month renting AI intelligence from OpenAI and Google. Here is how to own your AI infrastructure outright with NVIDIA DGX Spark, run Nemotron and open-source models locally, and eliminate per-token costs forever.
One email, most weeks
What actually changed in AI and what to do about it. No pitch, and you can leave in one click.